evaluate(). That call has a shape: datapoints in, an executor, a set of evaluators, a group. This page explains each part, the trace they produce, and how the scores are stored.
Datapoints
A datapoint is the unit of work.datais whatever the executor receives. It can be a primitive, a dict, or a deeply nested object. Whatever shape you put in, the executor’s first parameter has to match.targetis optional. It’s the reference value evaluators compare against. You can omit it entirely if your evaluators don’t need it (for example if an evaluator only checks output format).metadatais optional. Use it to filter or query datapoints later: model name, category, source dataset, anything you want on the row.
LaminarDataset. See Datasets for dataset-backed runs.
Tasks and trials
Each datapoint is a Task: one test case. Each execution of a Task in a run is a Trial. By default every Task runs once, so a run has one Trial per Task. Settrials to run each Task several times, which is useful when your agent is non-deterministic and one sample is too noisy to trust.
Every Task has a string task id, and all of its Trials share it. Tracevell uses the task id to match rows across runs, so set one explicitly when you want comparisons to stay stable as your datapoint list changes.
- TypeScript
- Python
france, three for japan. Each Trial gets its own trace and its own scores. In the run’s datapoint table, Trials are grouped under their Task, oldest first, and the Task row shows the average of its Trials. The run’s average score weighs every Task equally, however many Trials it has.
The task id is resolved in this order:
- Explicit
taskId/task_idon the datapoint. - The dataset row’s task id, when the datapoint comes from a Tracevell dataset.
- The datapoint’s position in the source data, as a string (
"0","1", …). This is the position before anytake/select/shuffle, so running a subset of the dataset keeps each datapoint’s task id.
foo#2, foo#3, and the SDK logs a warning. In Python, Datapoint accepts both task_id and taskId.
Executor
The executor is the function under test. It takesdata and returns anything.
The executor is your system boundary. Score what it returns, not what it does internally. If you want to score a tool call or an intermediate step, return that value from the executor.
Evaluators
An evaluator takes the executor’s output and (optionally) the target, and returns a score.- A number: one score dimension, named after the evaluator key.
- A dict of numbers: many score dimensions from one function. Useful when one pass over the output produces multiple metrics (
{ "precision": 0.9, "recall": 0.8 }).
span_type = 'EVALUATOR'), so you can inspect the score alongside the input that produced it.
Two kinds of evaluator you’ll actually write
- Code evaluators. Pure functions. Exact match, regex, JSON schema check, string length. Fast, deterministic, free.
- LLM-as-a-judge evaluators. A function that calls an LLM to score the output. Use when code can’t capture the quality dimension (tone, helpfulness, faithfulness).
Groups
A group is a name you give related runs. Tracevell uses it for two things:- The progression chart on the evaluations page shows the average of each score dimension over time for the group. This is how you see regressions.
- Side-by-side comparison between two runs is only enabled for runs in the same group.
capitals whether you’re running gpt-5-mini, gpt-5, or a fine-tune.
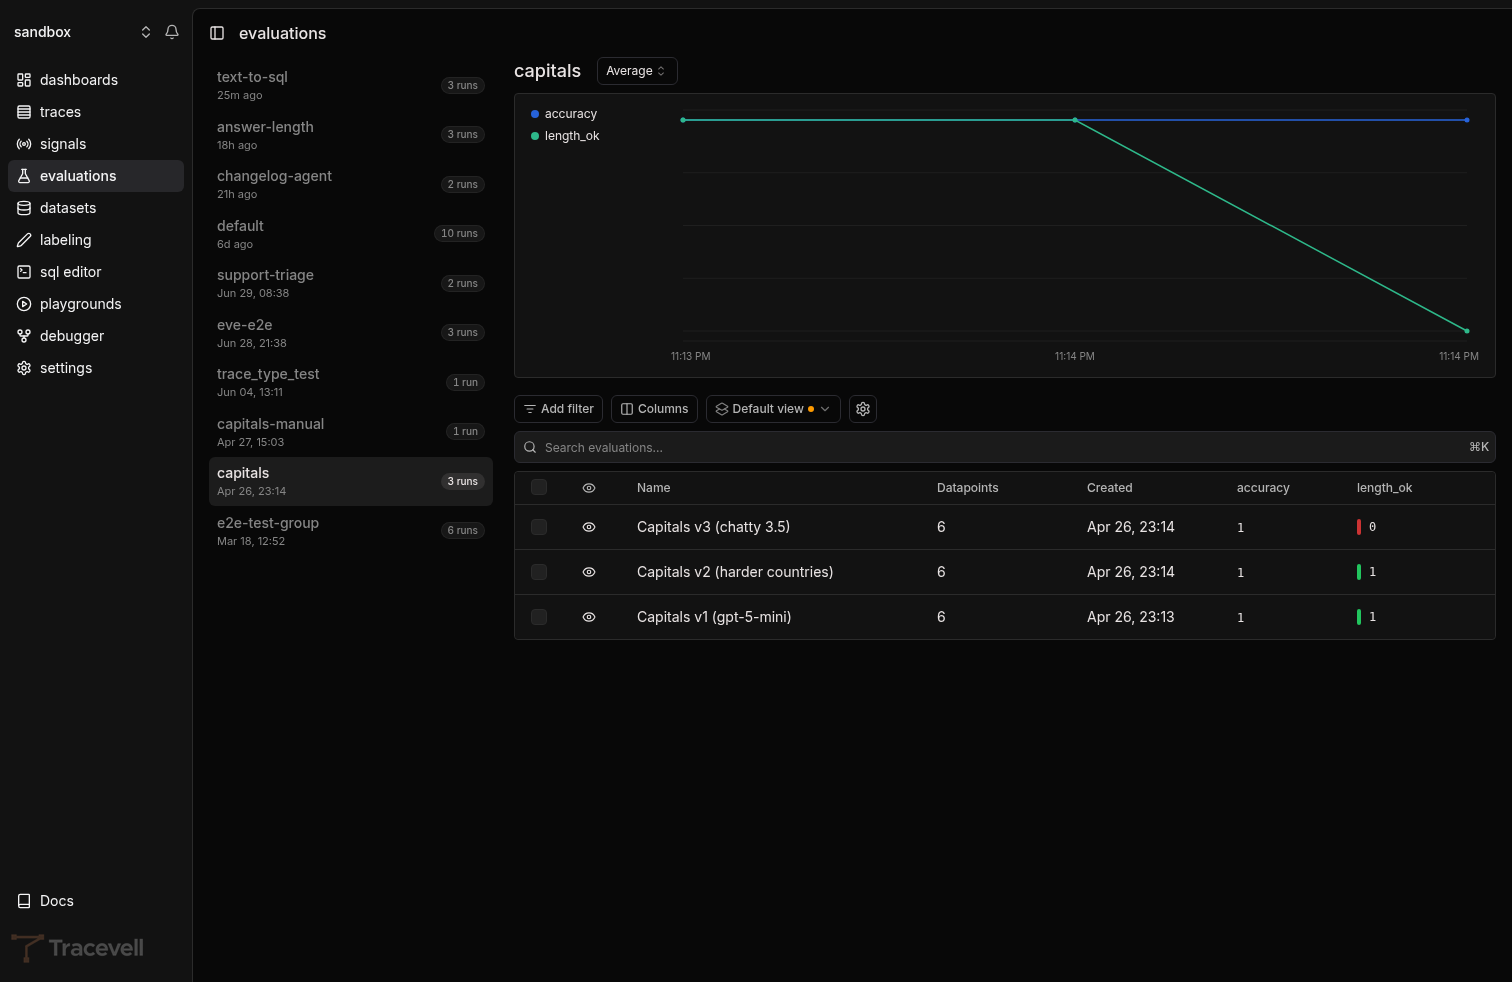
Three runs in the capitals group. length_ok regressed on the most recent run; accuracy stayed flat
The trace every trial produces
Every Trial becomes a single trace with a known shape:- Root span:
EVALUATIONspan covering the entire Trial. - Executor child: one
EXECUTORspan with the executor’s input and output. - Any LLM / tool spans your executor makes, auto-instrumented, nested under the executor.
- Evaluator children: one
EVALUATORspan per evaluator, each recording the score and the input it scored.
accuracy check:
What gets stored where
- Postgres
evaluations: one row per run. Holds the name, group, and metadata. - ClickHouse
evaluation_datapoints: one row per Trial per run. Holdsdata,target,metadata, executor output, scores,task_id,trace_id, duration, cost. The SQL editor exposes it asevaluation_trials(evaluation_datapointsstill works as an alias). - ClickHouse
spans: the EVALUATION / EXECUTOR / EVALUATOR spans and everything nested under them.
Next steps
Compare runs
How the progression chart and side-by-side comparison work.
Datasets
Point
evaluate() at a Tracevell dataset instead of a hardcoded list.Manual API
When
evaluate() is too opinionated: the lower-level LaminarClient.evals API.